
ItInsightsWorld Explainer: OpenAI’s Shared Quota Rules for ChatGPT and Codex
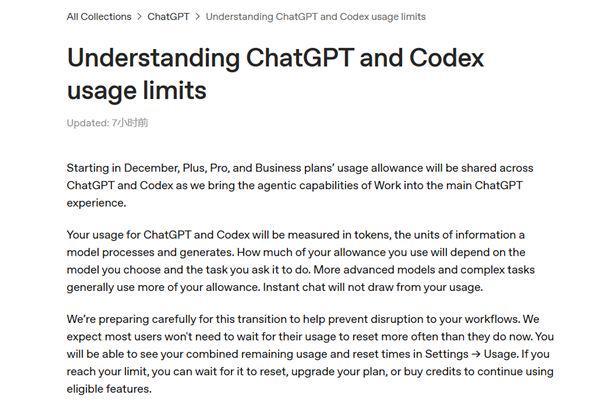
OpenAI has said that ChatGPT and Codex will draw from one shared quota, measured in tokens, rather than being tracked as isolated allowances. The main determinants of how quickly that allowance is used are the model selected and the complexity of the task: stronger models and more demanding work consume more tokens.
Instant chat and connected balances
Instant chat is excluded from the shared quota, so ordinary conversations in Instant mode remain unaffected. For paid users who use both ChatGPT and Codex, the two balances are linked; additional spending on either service reduces the amount available for the other.
Checking usage after the transition
OpenAI states that it has prepared for the transition and expects most users not to face reset waits more frequently than before. Users can check a combined remaining quota and the next reset time through the ChatGPT Settings—Usage page.
- Wait for the automatic reset.
- Upgrade the subscription plan.
- Purchase points to continue.