
Binance After the $6.3B Hack: A Plain-English Case Review of What Worked, What Did Not, and What You Should Copy
By James Hartley, IT Insights — General desk case review
Read the conclusions first
Most coverage of this story stopped at the headline number. The more useful story is buried in the sequencing: what the platform said, when it said it, and which pre-existing mechanisms did the heavy lifting while everyone watched the withdrawal queues. That sequencing is what ordinary readers can actually reuse, whether they hold crypto, keep money in a neobank, or simply store corporate data on someone else's cloud.
Three conclusions up front. First, the stabilisation reported this week is not luck or goodwill — it is the output of three mechanisms that were already in place before the attack: a pre-funded company backstop, the ability of stablecoin issuers to blacklist and freeze suspect balances on-chain, and a standing transparency channel that customers could check for themselves. Second, a "flows are back to normal" statement is a liquidity signal, not a security verdict; the security verdict is the post-incident investigation report, and it has not been published yet. Third, the reusable lesson is procedural: how fast a platform recovers tells you far more about how well it was run than how big its marketing budget is.
The case, in order
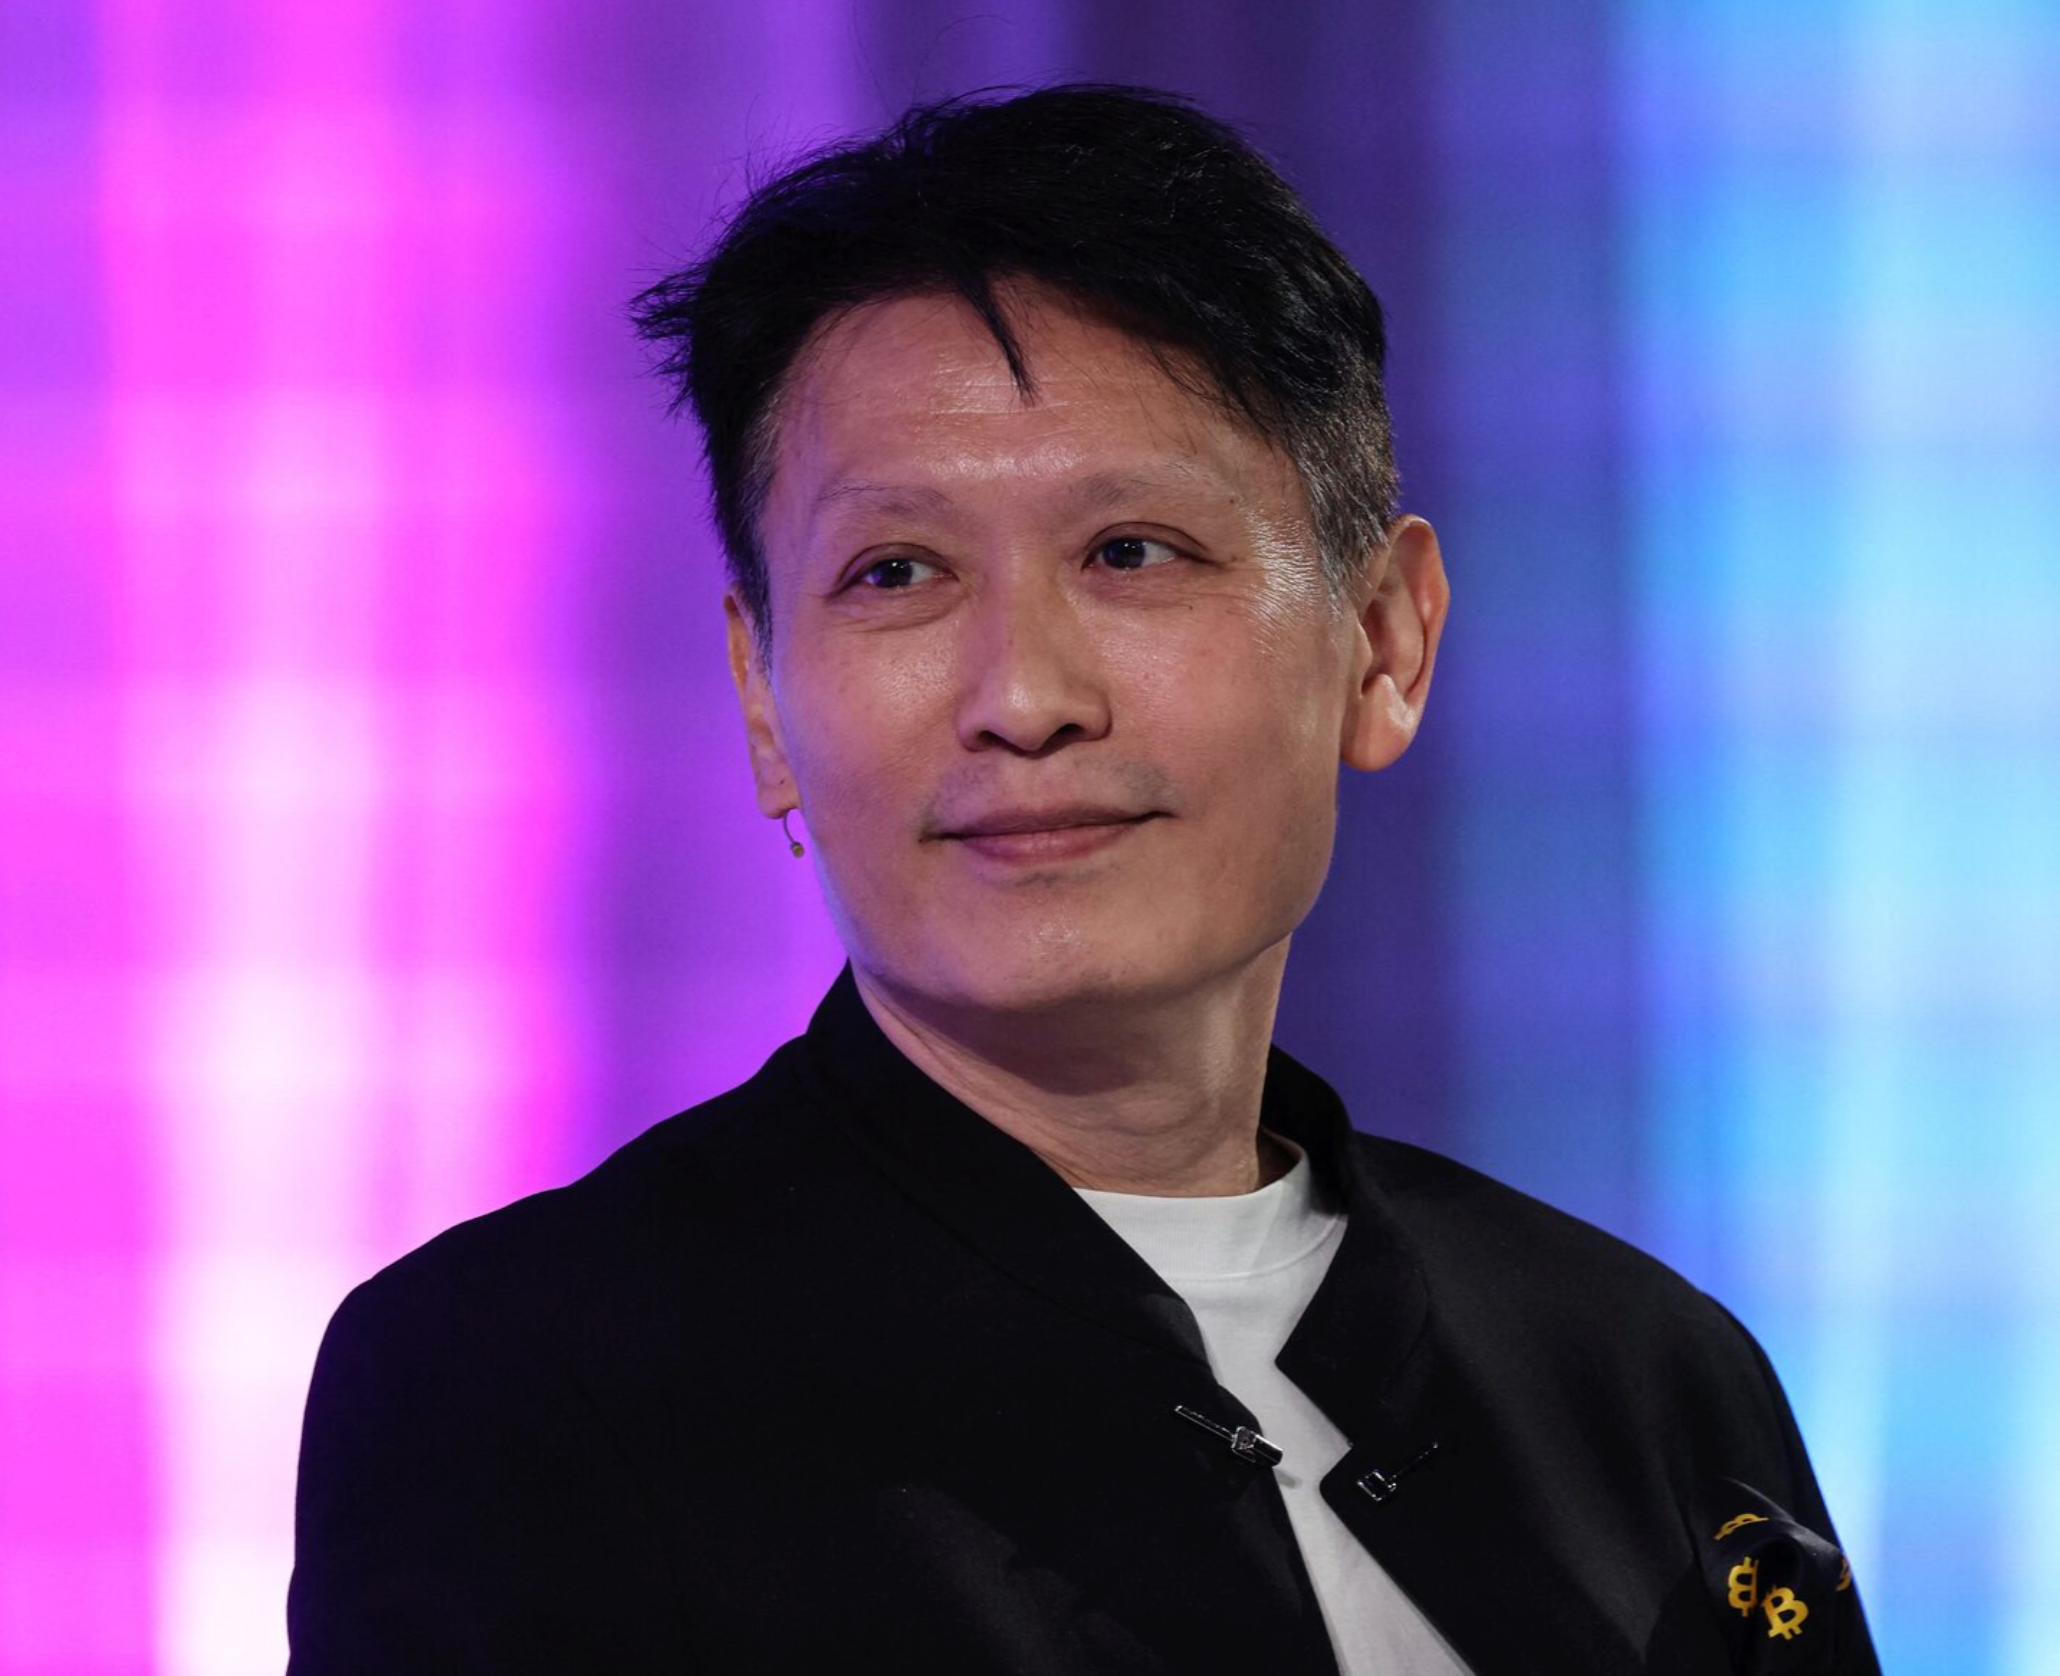
Reuters reported on November 3 that Richard Teng, who serves as Binance co-chief executive, spoke on Tuesday at an event during Hong Kong Fintech Week. His public position, condensed: the company's financial condition is very solid; hour-by-hour money flowing in and out of the platform is now "basically back to normal"; 95% of the affected tokens have been made good; and a post-incident investigation report on the $6.3 billion cyber theft will be released at an appropriate time.
Reconstructed against the company's own disclosures, the operational sequence looks like this:
- Loss detection and containment (last week). The exchange disclosed that it had been hit by what is being described publicly as one of the largest — possibly the largest — thefts in financial history, with $6.3 billion involved.
- Front door temporarily shut. Withdrawals were paused while the platform scoped the damage, a step that is always politically toxic and often technically necessary.
- Reopening under pressure (last Sunday). Withdrawals were switched back on. The predictable wave of exit requests arrived first, then subsided.
- Peak outflow measured (as of Monday). The company disclosed that net customer withdrawals had reached 4.72 billion dollars.
- Steady state asserted (Tuesday, then reported on November 3). Hourly inflows and outflows described as "basically back to normal", with 95% of affected tokens replenished.
On the intrusion itself, Teng's earlier characterisation was blunt: this was a "complex attack" tied to a compromised laptop, and it involved malware designed to erase its own traces, which raises the difficulty of tracing the attackers and moving the investigation forward. That single detail — anti-forensics built into the toolkit — is the clearest signal in the whole case that the target was chosen and the operation was rehearsed, not opportunistic.
Three mechanisms that did the actual work
1. A backstop that existed before the bad day
Recovery percentages mean little without knowing what funds them. In its third recovery update, published on October 31, the company said it had set aside more than $6.34 billion of its own money to cover the hacked losses and that roughly 90% of affected assets had been replenished at that point. Read together with the 95% figure Teng gave on Tuesday, the numbers form a visible curve rather than a miracle: the position was being closed asset class by asset class, from a pool that had already been earmarked. Reuters' explainer on the insurance mechanics of this episode notes that Binance created its Secure Asset Fund for Users (SAFU) in July 2018 as an emergency reserve to protect users in extreme cases — a five-year-old piece of infrastructure that only matters on a day like this one.
2. On-chain containment, which is not the same as recovery
Because much of the value moved as stablecoins, the theft hit contracts whose issuers keep a freeze function. CoinDesk reported that Tether froze more than $1.56 billion of USDT and Circle blocked about $823 million of USDC connected to the incident, with other actors taking similar steps, while quoting security specialists who warned that freezing and recovery are separate questions. For a general reader the takeaway is sharp and slightly counter-intuitive: a decentralised-seeming asset can be switched off by a centralised counterparty within hours. That is a real safety property, and it is also a real concentration of power.
3. A verification channel customers could check themselves
The third mechanism is the least dramatic and probably the most durable. Major exchanges now publish recurring proof-of-reserves reports; Binance's are issued monthly and are built on a Merkle-tree structure that lets an individual user confirm, from a record identifier, that their own balance was included in the liabilities snapshot rather than simply trusting a headline ratio. On the day of a crisis, this is what converts "take our word for it" into "check it yourself". It also has limits readers should know: a reserves snapshot covers on-chain assets and selected tokens, it is a photograph at one timestamp, and it does not disclose an exchange's off-chain obligations or total leverage. Useful, not conclusive.
Three incidents, one comparison
Placing this case next to the two most recent reference points makes the variables legible.
| Dimension | Binance, late October 2026 | Bybit, February 21, 2025 | Mt. Gox, February 2014 |
|---|---|---|---|
| Loss disclosed | $6.3 billion | About $1.5 billion (roughly 401,000 ETH) | 850,000 BTC claimed on bankruptcy |
| Entry point described | Compromised laptop plus self-erasing malware, in what management called a "complex attack" | Compromised signing interface on a cold-wallet transfer, not the wallet's private keys (per security researchers) | Years of quietly duplicated withdrawals exploiting a transaction flaw, plus weak internal controls |
| Who paid | Company funds set aside in advance, plus emergency reserve capacity | Exchange covered customer positions and returned deposits to normal | Nobody; customers went into bankruptcy proceedings for a decade |
| Disclosure style | Numbered recovery updates with percentages, then an interview at Hong Kong Fintech Week promising a post-incident investigation report | Fast acknowledgment, public timeline and FAQs, live solvency demonstration | Slow, inconsistent, then silence and collapse |
| Withdrawal handling | Paused, then reopened last Sunday; surge, then stabilisation, with 4.72 billion dollars of net withdrawals recorded as of Monday | Phased limits, then restored | Frozen while insolvency was concealed |
The pattern across the two modern cases is that a breach of the signing or approval layer — not the vault itself — is the current failure mode of choice, and that recovery now runs on two clocks: the on-chain clock of freezes and the reputational clock of updates. Mt. Gox is the control group: same category of asset, no backstop, no cadence, no verification channel, and a customer base that never got a real answer.
What the pending report still has to answer
Teng has said the post-incident investigation will come "at an appropriate time". Until it does, five questions define whether this case is a template or just a well-funded rescue. The first is the authorisation path: how did a compromised laptop end up with enough standing to approve outbound transfers of this size, and how many people or devices had to sign? The second is key management and the signing system, which is precisely where the industry's most damaging recent incidents have concentrated. The third is a minute-by-minute timeline from first anomaly to withdrawal halt. The fourth is the remediation list — what has been changed, with dates. The fifth is whether any independent firm attests to the findings. Well-run technology organisations treat this document as standard practice rather than damage control: the widely copied site-reliability convention is a written, blameless post-mortem covering detection, impact, root cause and follow-up actions, published promptly once an incident is resolved.
There is a signalling point here too. The venue for this update was Hong Kong Fintech Week, and the audience at such events is regulators, institutional allocators and compliance teams as much as retail users. Choosing that stage, on the record, with a date-bearing Reuters story behind it, is itself a governance act: it makes the promise of a published post-incident investigation harder to quietly withdraw.
Five misconceptions this case keeps producing
- "Reopened withdrawals means it is safe now." Reopening means the platform believes it can meet demand. The cause is a separate, still-undisclosed question.
- "Frozen funds means stolen funds." Freezing blocks movement of specific balances; recovering them is a legal and technical process that may never complete.
- "95% replenished means 95% traced." Replenishment says the platform covered the hole from its own resources. It says nothing about how much of the stolen value followed.
- "Proof of reserves proves solvency." It evidences on-chain coverage of listed assets at a timestamp; it is not an audit of liabilities, leverage or off-chain exposure.
- "Big enough to survive it means big enough to prevent it." Scale buys a backstop. It does not buy immunity from a human or endpoint failure.
Your action checklist
Seven checks that generalise to any platform you trust with value — exchange, brokerage, cloud provider, or a work SaaS account.
- Read the funding source, not the headline percentage. Ask which balance sheet is absorbing the loss and whether it was pre-funded or improvised this week.
- Look for the update cadence. Numbered, dated updates with changing figures indicate an incident process; a single reassuring statement indicates a public relations one.
- Verify with your own hands where you can. If a platform offers self-verification — a Merkle proof, a solvency snapshot, a downloadable statement — run it on your own account rather than reading the aggregate.
- Track the withdrawal lane. Fees, delays, limits and phased queues are the earliest honest indicators of stress, usually ahead of official statements.
- Keep exposure inside your own recovery capacity. Size positions on a custodian at the amount you could survive being illiquid for the number of days the incident lasts — in this case that window ran over a week.
- Split custody by function. Active trading balances on the platform, long-term holdings wherever you control the keys or the contract.
- Demand the post-mortem in writing. Follow-ups, dates and third-party attestation are the difference between learning and forgetting.
FAQ
Did customers actually lose money in this incident?
Not from the theft itself, on the company's account: Teng said 95% of affected tokens had been made good, and the earlier recovery update said company funds were covering the hole. The costs customers did bear were opportunity and timing — the 4.72 billion dollars of net withdrawals recorded as of Monday largely reflects people moving assets at whatever terms the platform allowed during the pause.
Why did withdrawals spike when the service came back?
A queue that has been shut always empties fast on the first day. The company's own framing was that the surge came after users regained access, then flows stabilised; the meaningful data point is the hour-by-hour trend, which management now describes as "basically back to normal".
Does this change how safe central exchanges are?
It sharpens the same warning the industry has carried since 2014: an exchange is a counterparty with an operational risk profile, not a vault. What has genuinely improved is the toolkit after a failure — self-funded reserves, issuer freezes, published proof-of-reserves — which is exactly the layer Mt. Gox customers did not have.
Is there a way to tell whether a platform is over-promising?
Watch three things: does every update carry a date and a number that moves, does the platform publish a post-incident investigation report rather than only reassurance, and does it name remediation steps with owners and deadlines. Silence on the third point is the loudest signal.
When will we know what really happened?
Not yet. The post-incident investigation into the $6.3 billion theft is still pending, and the anti-forensics in the malware — components built to erase their own traces — is precisely why Teng has publicly framed the investigation as difficult rather than slow.
Bottom line
Recoveries make headlines; post-mortems make industries safer. The next time a platform you use announces an incident, skip the reassuring adjectives and go straight for three nouns: who is funding the fix, what is the update schedule, and when does the written investigation land. Those three questions are the whole case in portable form — and they apply just as cleanly to a cloud vendor outage or a bank app that quietly disappears for a weekend as they do to a billion-dollar crypto theft.
This case review is prepared by the IT Insights general desk. Suggestions for follow-up analysis are welcome at contact@itinsights.com.