
Jevons or Gartner? Eleven Questions Cloud Architects Should Ask About AI Chip Depreciation
Ask two architects about the AI buildout and you get two answers from two different spreadsheets. One sees demand outrunning every capacity plan on the table; the other sees assets that may be worth less than the debt raised against them. The IT Insights CloudComputing desk has been following both lines of evidence — a research forecast, a GPU rental chart, a week of hyperscaler earnings calls — because the question that matters inside a procurement review is never which camp wins, but which assumption your own contract is underwriting. So the topic is rebuilt below as a decision list: eleven questions that surface when a team has to size, price, route and defend AI compute, each with a short answer and the follow-up that changes the bill.
Q1. What exactly did Gartner put on the table?
Short answer: an arithmetic gap, not a verdict.
A couple of weeks ago the research firm warned that AI providers will spend close to $1 trillion on infrastructure in 2026 and another $6 trillion between 2027 and 2030. To fund that, carry the borrowing and still clear a 12% return, AI data center owners would need about $8.5 trillion in revenue through 2030, while the AI revenue actually reaching those data centers is expected to be $3.6 trillion at most. On that arithmetic, more than $3.5 trillion of the spending could be exposed to write-downs by 2030, and more than 80% of neoclouds will no longer exist as independent companies. The forecast, published on Gartner's own newsroom on 14 October 2026, is a risk estimate under stated assumptions rather than a claim that the full amount will be written off; the cumulative revenue shortfall it implies — roughly $4.9 trillion — was the number Fortune chose to headline.
Follow-up that matters: if your platform is priced on the assumption that a GPU earns for half a decade, that exposure reaches you through renewal terms, take-or-pay clauses and collateral requirements, not through somebody else's income statement.
Q2. Does the Jevons paradox rescue the revenue side?
Short answer: it explains the demand curve, not your utilization rate.
The Jevons argument is that a resource which becomes more available finds new uses, so total consumption can rise even as unit price falls. Cars make it concrete: better fuel economy lowers the cost per kilometer, so people drive further and may buy more fuel overall; cheaper petrol invites more driving, and a price rise pushes some commuters onto public transport. On the AI side, Epoch AI estimates that the price of reaching a given benchmark score has fallen by roughly 13 times a year since 2023, measured on the benchmarks it tracks, with the usual caveats about how those are chosen — a decline that started in 2023 and has run through 2025 without reversing.
Two qualifications belong in any cloud budget built on this logic. First, nothing guarantees that demand grows faster than prices fall. Second, Epoch's own follow-up analysis is more granular and less tidy than a single headline number: across the performance milestones it tracked, the annual rate of price decline ranged from 9x to 900x, varying sharply by task and by which capability level you hold fixed (epoch.ai, data insights on inference price trends). A flat “13x per year” assumption applied to every workload is the most common way teams under-price a token factory and over-price a fleet.
Q3. Are the “old chips” really keeping their value?
Short answer: longer than the straight-line models assumed — but the premium is a spread, not a global price.
Recent market telemetry points the same way. A chart published by a16z, built on Ornn rental data as of Oct. 19, compares what each major Nvidia generation rents for today against a simple projection: take the first rent observed for that chip and let it fall in a straight line to zero over six years, roughly how hyperscalers write these servers off in their accounts. Every generation now rents above that line — the A100 by 9%, the H100 by 54%, the B200 by 111% and the H200 by 143%. Most of that gap opened after April, when token demand took off, which is consistent with Jevons at work, although the chart alone cannot prove the cause.
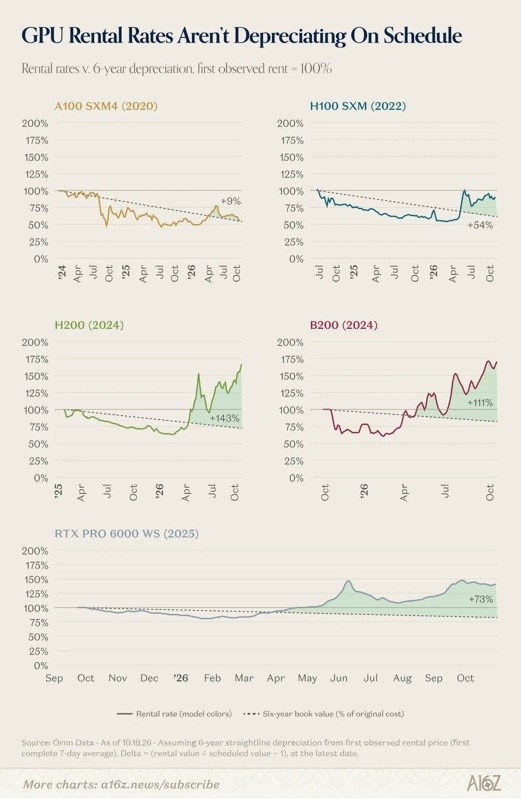
Public price indices let you sanity-check the same story from a different angle: the SemiAnalysis GPU Pricing Index recorded an H100 at about $3.46 per GPU-hour in September 2026, while independent comparators list typical on-demand H100 rates near $3.83 across more than sixty providers and entry-level A100 40GB capacity from $1.99 (semianalysis.com; getdeploying.com; northflank.com). Marketplace operators in the same regions undercut hyperscaler list rates for identical silicon, and the gap moves region by region. Two caveats from the original analysis still bite: for most of their lives these chips rented below that line, and rent is not profit — a chip can rent well and still lose money for its owner once power, cooling, networking, facilities and the cost of borrowing are paid.
Procurement implication: the “above the line” premium is an average that hides negotiation. If you are on a legacy reservation priced from 2023 list rates, you may be paying the premium without capturing it.
Q4. Rent or buy — which answer survives a depreciation clock you do not control?
Short answer: neither, unless utilization and contract term are modelled together.
Commitment structure is the second lever after chip choice. Published 2026 build-versus-rent frameworks put one-year reserved terms somewhere between 5% and 38% below on-demand, and warn that the average enterprise GPU is busy only a small fraction of the hours it is paid for; the same logic sits underneath GPU-backed lending, which only works if the collateral holds enough value over five to six years to cover the loan (eknix.com; aethir.com). That is precisely the assumption the Gartner scenario questions.
Use the rental data in Q3 as a market signal, not as your business case. Ask what your fleet does when the next generation lands in volume: if your workload is interactive and latency-bound, the newest hardware is the only honest answer; if it is bulk and deferrable, the cheapest tokens you can produce are the ones from silicon that is already paid off.
Q5. Which tokens belong on which silicon?
Short answer: there is no single token market, so there is no single correct chip strategy.
The Economist recently described compute as the new oil, and the comparison is useful in one direction and misleading in another. The token is the barrel, the “thing” the customer actually buys. Each GPU generation is an oil field: some wells are cheap to pump and yield better crude, so cost per barrel is low; others are harder and produce lower-quality output at a higher cost. For GPUs, the cost of producing a token is tied largely to how much energy each generation needs, and to whether it can handle the work at all. When prices are high every well pumps, even the expensive ones; when they fall, the costliest wells shut first. Since April, demand has been high enough that even the A100 is needed and every generation rents above the line. When a new generation arrives in volume it becomes the new cheap well, prices fall and the oldest chips are the first to be switched off — Microsoft, for instance, plans to scale its own Maia accelerators to multi-gigawatt deployments from 2027, claiming 40% more tokens per megawatt, a figure not yet independently verified.
The flaw in the oil analogy is that it treats every barrel as identical. Interactive and agentic work needs low latency and the newest, fastest memory. Bulk work — processing documents overnight, generating synthetic data, running evaluations — cares mostly about cost and barely notices latency, so a fully paid-off chip whose remaining costs are power, cooling and upkeep can be the cheapest way to make those tokens. A concrete recent example is Jev, from TypeSafe AI, a model that returns structured decisions rather than text and that its makers claim is hundreds of times cheaper than a large language model; models like that could move much agentic decision-making off expensive LLMs and look well suited to older hardware, although TypeSafe does not say what it runs on. At the other extreme, frontier models keep getting bigger and increasingly sparse, activating only a small part of the model per token as in Mixture of Experts architectures, where the bottleneck becomes memory capacity and fast chip-to-chip links rather than raw compute. For those, the rack rather than the chip is the unit of work, and an older GPU is not so much too slow as too small and too isolated.
That is the barbell: giant models pull toward the newest rack-scale systems, small and specialized models live happily on older silicon, and the squeeze falls on the middle — chips that are neither frontier nor paid off, still carried on the books at a high value. A lot of the 2024 and 2025 spending sits right there.
Q6. Can my estate govern a mixed-generation fleet?
Short answer: scale decides this, not tooling.
A cloud data center a decade ago ran different types of CPU, memory, storage and networking, and the job was matching workloads to a fairly predictable menu. Those servers aged gracefully: each new CPU generation was only modestly better than the last, so an older server kept earning for years, rather like a rental car where last year's model is nearly as good as this year's. Today the menu is far richer. Next to the CPUs sit GPUs, TPUs and other AI accelerators, and inference is increasingly split into stages that run best on different chips — Nvidia announced Rubin CPX, a dedicated chip for the prefill stage, in 2025, then put it on the back burner, possibly until a later generation, in favor of decode-focused racks based on technology licensed from Groq. Add HPC, which often still needs high-precision math that many AI chips deprioritize, and the matching job gets harder while each generation ages faster.
The largest operators can afford that variety: with enough scale they keep many kinds of hardware busy and route each job to the cheapest chip capable of doing it. Smaller data centers cannot, and for them the general-purpose GPU remains the safest bet, because it can step down from training to inference to batch work as it ages. Specialized parts are cheaper per task but more fragile as assets, since they lose that ability to start a second and third career. Dedicated on-premises installations are a different case again: a company running well-understood workloads can pick a configuration that fits them closely and does not need to chase every generation, where state-of-the-art silicon matters mainly for training custom models and perhaps a few GPU-accelerated solvers.
Q7. Who sets the depreciation clock on your assets?
Short answer: whoever draws the next chip.
Many of the big operators spread the cost of these servers over about six years in their accounts, but that is a bookkeeping convention and says little about how long a chip actually earns more than it costs to run. That economic life is decided upstream by the people designing the next chip: Nvidia's annual cadence, the tokens-per-watt gains each generation brings, new memory standards and number formats, and the software that keeps old chips useful together. In that sense the silicon roadmap dictates the real depreciation timeline.
Seen this way, owning your own silicon buys influence over your own clock. Microsoft with Maia, Google with TPU and Amazon with Trainium can shape when their own fleets become obsolete, even if demand and competitors still have a vote, while a neocloud renting out Nvidia GPUs lives on a clock set by its supplier and its customers. And Nvidia sits on both sides of the table: it sets the pace that erodes the value of its customers' fleets and — at the same time — has, according to a recent piece in The Economist, agreed to cover up to $300 billion of its customers' debt used to buy its chips should those customers be unable to repay. A faster cadence sells more new chips and weakens the collateral securing those loans. When Jensen Huang posted in August that an A100 remains useful until 2029, he was making a technical point, but he also has a stake in that tradeoff.
Q8. What does the rental-car analogy actually prove?
Short answer: a supplier's pricing decision can erode its customer's fleet value.
The deeper question behind Gartner's numbers is who will own the chips when the market turns. Rental car companies are the closest working model: they buy fleets largely with borrowed money, pledge the cars against the loans, and make or lose money on what those cars fetch at resale. In early 2024, Hertz sold off about 20,000 electric vehicles and booked a loss of about $245 million. Hertz pointed mainly to high repair and collision costs, but weak resale values played a part too, and Tesla's price cuts on new cars had pushed down the value of used ones. GPUs carry the same risk in a stronger form: each new generation is a far bigger step than a new model year, the market for used chips is thinner and more specialized than the market for used cars, and power, unlike parking space, is scarce.
Q9. What did last week's earnings calls add?
Short answer: capacity is still the constraint, and usage is no longer the same thing as revenue.
Last week's calls supplied the newest signals. Meta, which reported a week earlier, narrowed its 2026 capital spending to $135–$145 billion and cited growing infrastructure costs and payments to third parties for AI tokens. Then Microsoft, Alphabet and Amazon reported: all three said demand for AI computing still runs ahead of the capacity they can bring online, and Microsoft and Google are even renting capacity from third parties to keep up. Between them, these three plan to spend close to $600 billion in 2026, and Alphabet and Amazon both said they will spend significantly more in 2027.
Four details on those calls matter for architects. Microsoft credited part of Azure's growth to “continued efficiency gains across our CPU and GPU fleet,” a reminder that getting more out of the fleet you already own is part of the business, exactly as it is for a rental car company. Amazon said short-term capacity on its previous-generation Trainium chips now rents at a premium compared with the first half of the year, which supports the a16z chart's insight on Amazon's own silicon, and that inference is now well over half of AWS's AI revenue — the varied, price-sensitive work where older and specialized chips compete best. Google is now selling complete TPU systems for customers to run in their own data centers, with Amazon planning to sell Trainium outside AWS from late 2027: owning a silicon roadmap is becoming a product the hyperscalers can sell, which means more of the market may live on their roadmaps rather than only on Nvidia's. And investors were reminded that more usage does not automatically mean more revenue — Alphabet lost about $500 billion of market value in a day after admitting that answers from AI Mode in Google search earn less than traditional search ads, according to The Economist. Since advertising pays for much of this buildout, that matters to everyone buying chips. More of the money is now borrowed: Meta, Alphabet and Amazon all reported negative free cash flow, and even Microsoft, still cash-positive, announced $25 billion of new bonds the day after its earnings call.
Q10. What did Jevons himself conclude?
Short answer: growth and casualties are the same event, seen from two sides.
In 1865, in The Coal Question, the economist William Stanley Jevons observed that more efficient steam engines did not reduce Britain's coal consumption but increased it, because cheaper power found many more uses. His point held: Britain's coal consumption kept growing as its engines improved, even if efficiency was not the only reason. It did not save every mine — the owners of the least efficient pits still went under as the industry grew. Something similar should be expected here: AI demand will likely keep surprising on the upside, and a good part of the money that built the first generations of this infrastructure will likely still have to be written down. Both outcomes come from the same roadmap, seen once from the buyer's side and once from the owner's.
Q11. Which non-silicon constraints should change your answer?
Short answer: power lead times and the compliance calendar, not hourly price.
Two constraints that rarely appear in chip-versus-chip debates decide most real deployments. The first is electricity. In 2024 the average time from an initial grid interconnection request to commercial operation had risen to nearly five years, against under two years in earlier eras, and several US markets now quote five to seven years for large loads (rmi.org; verse.inc). When energized capacity is the bottleneck, availability windows, region portability and contractual ramp schedules outrank a five-cent difference per GPU-hour in any honest TCO model.
The second is regulation. The EU AI Act entered into force on 1 August 2024 and becomes broadly applicable on 2 August 2026, with some obligations phasing in later (European Commission; artificialintelligenceact.eu). For cloud teams this converts provenance, logging and evidence retention into architecture requirements that must survive a provider change — which is a governance argument for keeping routing policy, telemetry schema and model-version lineage portable across the clouds you use, rather than binding them to whichever console is fastest to deploy today.
Comparison table: four ways to buy AI compute
| Route | Best fit | Main cost lever | Obsolescence exposure | Clause to demand |
|---|---|---|---|---|
| Frontier rack rental (newest generation, rack-scale) | Interactive, latency-bound, agentic traffic; custom training | Nothing cheap here — leverage is utilization | Highest: the next generation is the price reset | Generation-migration and repricing rights at each roadmap step |
| Self-silicon cloud (Maia, TPU, Trainium) | Bulk and deferrable inference; predictable serving shapes | Tokens per megawatt and per dollar | Set by the vendor's own roadmap, which it now sells to you | Roadmap-visibility notice periods before deprecation |
| General-purpose GPU IaaS across mixed generations | Multi-tenant platforms that must step workloads down as hardware ages | Routing each job to the cheapest capable chip | Moderate, if the fleet stays liquid | Ability to swap generation without breaking term commitments |
| On-prem dedicated fleet for known workloads | Well-understood pipelines, accelerated solvers, data-residency cases | Depreciation schedule you control | Yours to absorb; no second career for specialized parts | Resale and residual-value assumptions stress-tested in the business case |
Fast answers for the ops channel
- Should we book three-year capacity now to lock the price? Only for load you can name. Commitment terms can look cheap against on-demand while utilization turns the discount into a stranded cost.
- Is the A100 a dead asset? Not yet — it is renting above its straight-line curve — but it is a bulk-work asset, not a frontier one.
- Does inference or training age better? Inference is now the larger revenue line at the big clouds and the work older silicon handles best, so inference capacity has the more durable second market.
- Should we chase tokens-per-megawatt claims? Treat them as vendor statements until independently verified, then make the vendor commit them in writing.
- What if token demand doubles anyway? Then power is the constraint, not silicon — and grid lead times measured in years decide whether you can respond.
- Which risk is bigger: neocloud failure or owning the fleet? Supplier failure is a continuity question you can contract around; a write-down on hardware you own is one you cannot.
Four misconceptions that quietly distort the forecast
- “Cheaper tokens mean more revenue for whoever owns the chips.” Jevons reallocates spend across the stack; the demand it creates can flow to application builders and model providers rather than to whoever sells raw compute.
- “Six-year depreciation is a fact about hardware.” It is a convention about accounting; the economic life is set by the roadmap.
- “A chip that rents well is earning well.” Rent is gross, not net — energy, cooling, networking, facilities and interest are the real deductions.
- “All tokens are interchangeable.” Latency-sensitive work and bulk work price hardware completely differently, which is why one procurement policy for both usually fails.
Pre-contract checklist: eight numbers to nail down
- Your effective $/GPU-hour by generation, benchmarked against a public index rather than the list price in the quote.
- Modeled fleet utilization, not peak utilization, for every committed block.
- The repricing or migration clause that fires when the vendor ships a cheaper generation.
- Power and cooling assumptions written into the SLA, since energy dominates the cost of the newest workloads.
- Residual-value assumption for any capacity you own, tested against the supplier's release cadence.
- Which chip runs which workload class: latency-bound, bulk, and high-precision HPC.
- Portability of telemetry, logs and model-version lineage across regions and providers.
- A documented exit path for take-or-pay terms, including who absorbs the loss.
A 90-day action plan
- Days 1–15: split your token ledger. Tag every inference bill as latency-bound or bulk; the two classes lead to different hardware and different contract terms.
- Days 16–30: re-price the older generations. Pull live market rates for anything you have reserved; legacy rates from an earlier cycle are the most common hidden premium.
- Days 31–60: run the roadmap stress case. Assume a one-generation price reset in tokens per megawatt and see which commitments still make money.
- Days 61–75: fix the governance gaps. Put portable logging, lineage and evidence retention into the architecture standard, not into one provider's console.
- Days 76–90: diversify the clock, not just the vendor. Combine a self-roadmap provider, a mixed-generation general-purpose pool and a paid-off bulk tier so no single supplier sets your asset life.
The takeaway from both sides of this debate is the same, once you stop arguing about whether AI is a boom or a bubble. Demand can keep accelerating while individual assets still lose money, because efficiency gains and obsolescence are produced by the same roadmap. Jevons describes the crowd; the depreciation schedule describes your line item. Any cloud plan that answers only one of those questions is not a plan yet — it is a hope with an invoice attached.